Alpaca LoRA Training and Inference
This example demonstrates how to fine-tune and deploy Alpaca-LoRA on Beam. To run this example, sign up for a Beam account.Training
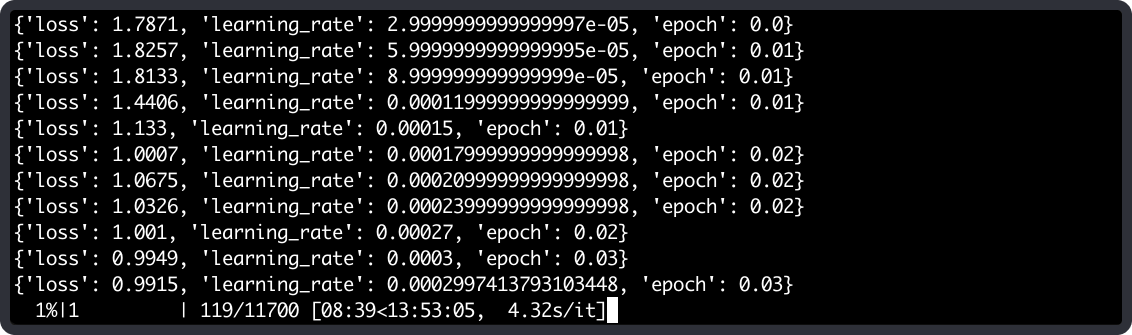
We’re going to implement the code in the Llama LoRA repo in a script we can run on Beam. I’m using the Instruction Tuning with GPT-4 dataset, which is hosted on Huggingface. The first thing we’ll do is setup the compute environment to run Llama. The training script is run on a 24Gi A10G GPU:This example only demonstrates the high-level workflow, so specific functions like
train are hidden. You can find the entire source code on Github.beam run command:
Deploying Inference API
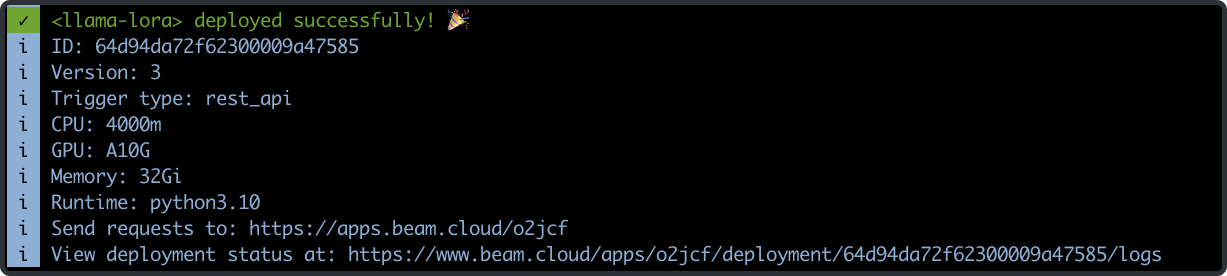
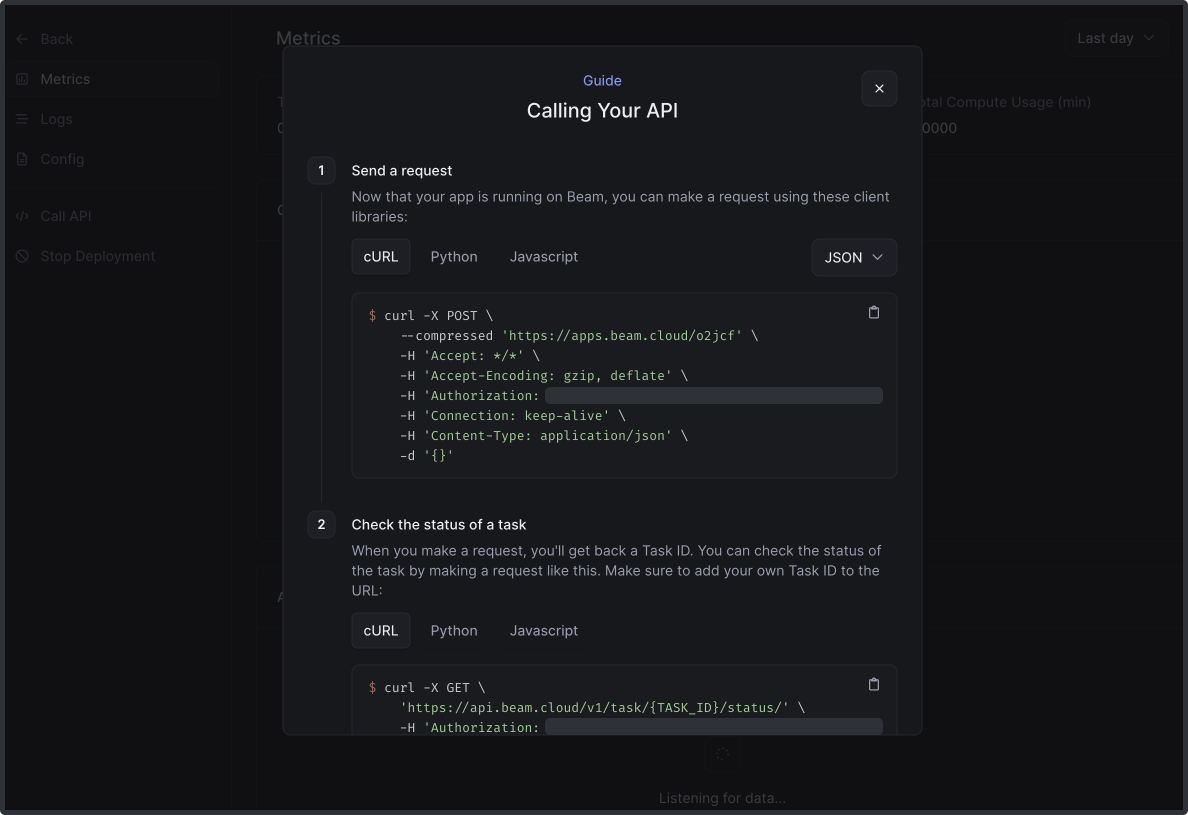
When the model is trained, we can deploy an API to run inference on our fine-tuned model. Let’s create a new function for inference. If you look closely, you’ll notice that we’re using a different decorator this time:rest_api instead of run.
This will allow us to deploy the function as a REST API.